Emotions shape perception, guide decisions, and structure thought. They form the intimate undercurrent of our cognition, yet are notoriously elusive and difficult to articulate. Our emotion decoding research seeks to address this paradox by developing new ways to externalize and communicate emotional experiences.
Today, we are introducing NOVA (Neural Observations of Video-evoked Affect), a large-scale dataset of emotion-evoking videos paired with EEG recordings. NOVA contains:
- 408 unique videos
- 3,408 EEG-Emotion-Video pairs
- 24 participants of diverse demographics
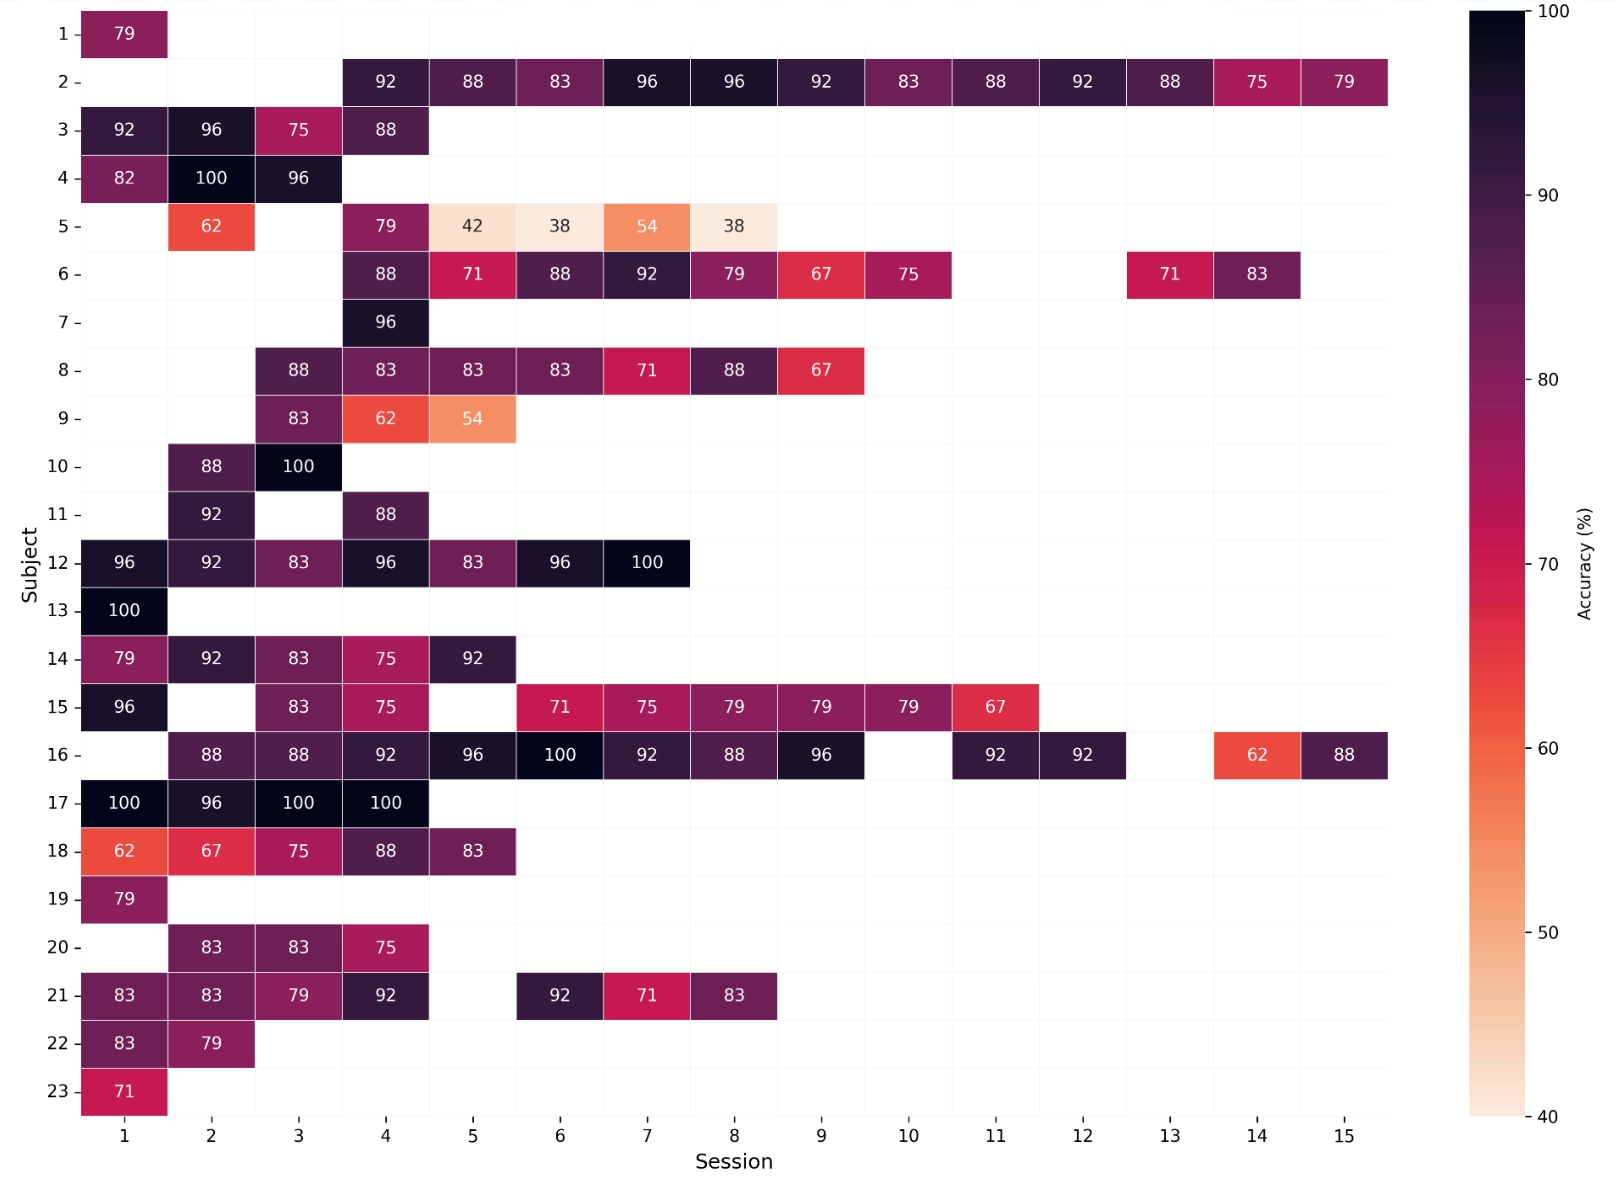
This makes it one of the largest EEG-Emotion datasets in the field. Using the NOVA dataset, we demonstrate state-of-the-art decoding performance of up to 75% accuracy with a single-subject model on a six-way emotion classification task (chance = 16.7%). This blog outlines the trajectory of our preliminary research, highlighting two key elements that drive our performance: label quality and signal representation.
Why Emotion?
At its core, this project echoes Alljoined’s ethos of building a human-centric future for AI and BCIs. Importantly, human intelligence is not purely logical or symbolic; it is embodied and intuitive. If AI systems are to meaningfully collaborate with us, they must interface with this dimension of experience. We aim to build adaptive systems that not only understand what you say but also empathize with how you feel – infusing artificial intelligence with emotionally-grounded human intelligence.
Furthermore, linguistic communication reduces nuanced and amorphous thoughts into diluted word representations. In recording the neural signals of emotional states, we strive to access the raw patterns of the experience itself. This opens the door to unfiltered forms of representation that will allow people to express themselves more authentically and understand one another on a deeper level.
Building NOVA From Scratch
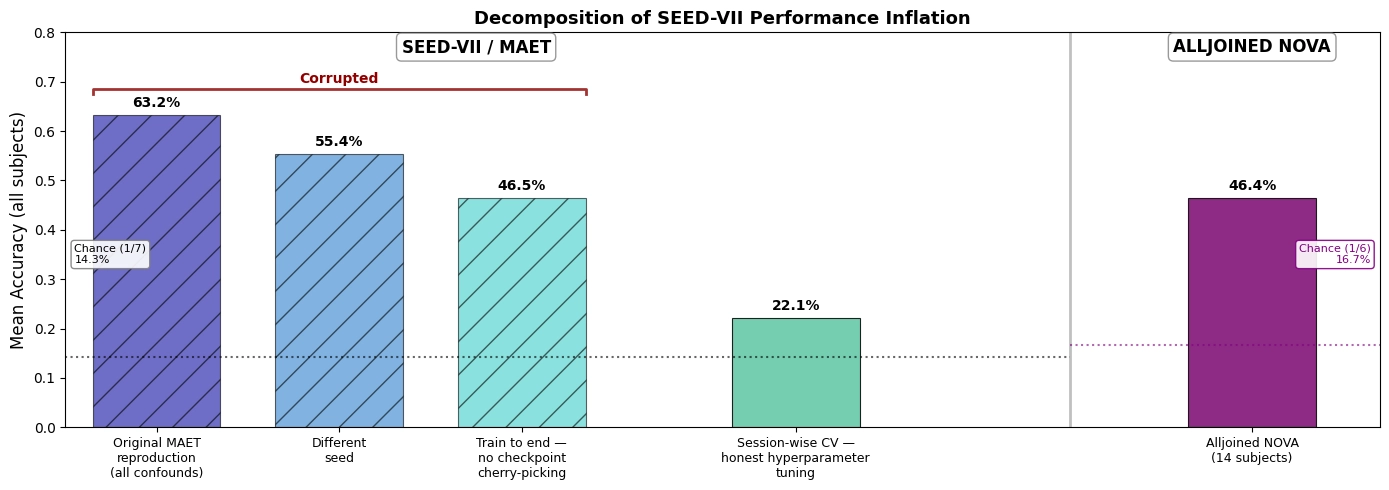
After surveying emotion decoding research, we found much of the recent high-profile work in the space to be fragile and confounded. Some reported accuracies relied on subtle methodological issues that inflate performance without reflecting real-world capability. Because Alljoined wants to build robust models that will work in real-world applications, we decided to design NOVA from scratch, with rigorous experimental controls and honest evaluation.
The Label Problem
The very qualities that make emotion an interesting research topic also make it difficult to measure. Emotions are fundamentally intertwined with perception, creating a self-reflexive limitation; in describing our emotions, we are trying to perceive a facet of perception itself. As a result, subjective reports are inherently unreliable: participants struggle to label their emotional states, and descriptions often diverge from physiological or behavioral observations. This metacognitive problem highlights exactly the kind of obscured communication that Alljoined seeks to solve. However, unraveling this problem requires confronting it in our own research methods first.
Unlike many other decoding tasks, which have a clear external ‘ground truth’, an accurate reference is inaccessible in emotion research. We know exactly what a participant sees when viewing a visual stimulus, but what a participant feels when viewing a movie scene remains largely opaque. The layers of mixed texture and tone of an emotional experience are unlikely to be captured by a single label or coherently conveyed in a participant’s description.
This matters because accurate labels are a critical component of efficient machine learning. In supervised learning, models are trained by pairing each datapoint (EEG epoch) with a label. The model ingests many instances of brain activity associated with a given emotion label, for example, all the EEG recordings of a participant viewing ‘sad’ videos. The model tries to learn the neural signature of ‘sad’ by identifying patterns that are consistent across these instances. However, if self-reported emotion labels diverge substantially from the neural activity of the participant's true emotional state due to the inherent difficulty of introspection, the signal the model is trying to learn becomes incoherent.
This is a major reason for the nascent state of emotion decoding research. The label problem cannot be fully solved, but it can be mitigated. NOVA attacks it from two angles: first, the sheer volume of the dataset (3,408 EEG-Emotion-Video pairs) allows consistent signal to overcome outlier noise, and second, through high-quality stimulus curation.
Experimental Design
Addressing the label problem requires maximizing the likelihood that a video reliably evokes the emotion it was designed to evoke. This is a challenging endeavor, especially when participants are of varying ages, cultures, and backgrounds. For example, a video of a dog being abandoned may make one participant feel sad for the dog and another participant feel angry at the negligent owner. Even on an individual level, emotional responses are often mixed and difficult to disentangle. For this reason, thoughtful curation is a critical component of NOVA.
The dataset’s 408 videos are curated through a rigorous three-stage review process: research assistants submit YouTube videos and movie scenes as candidates, critique one another’s selections, and only those that survive a final screening are admitted to the dataset. This process tests if stimuli universally elicit strong, discrete emotional responses across a variety of people. The videos that make it into the dataset are then incorporated into our experiments.
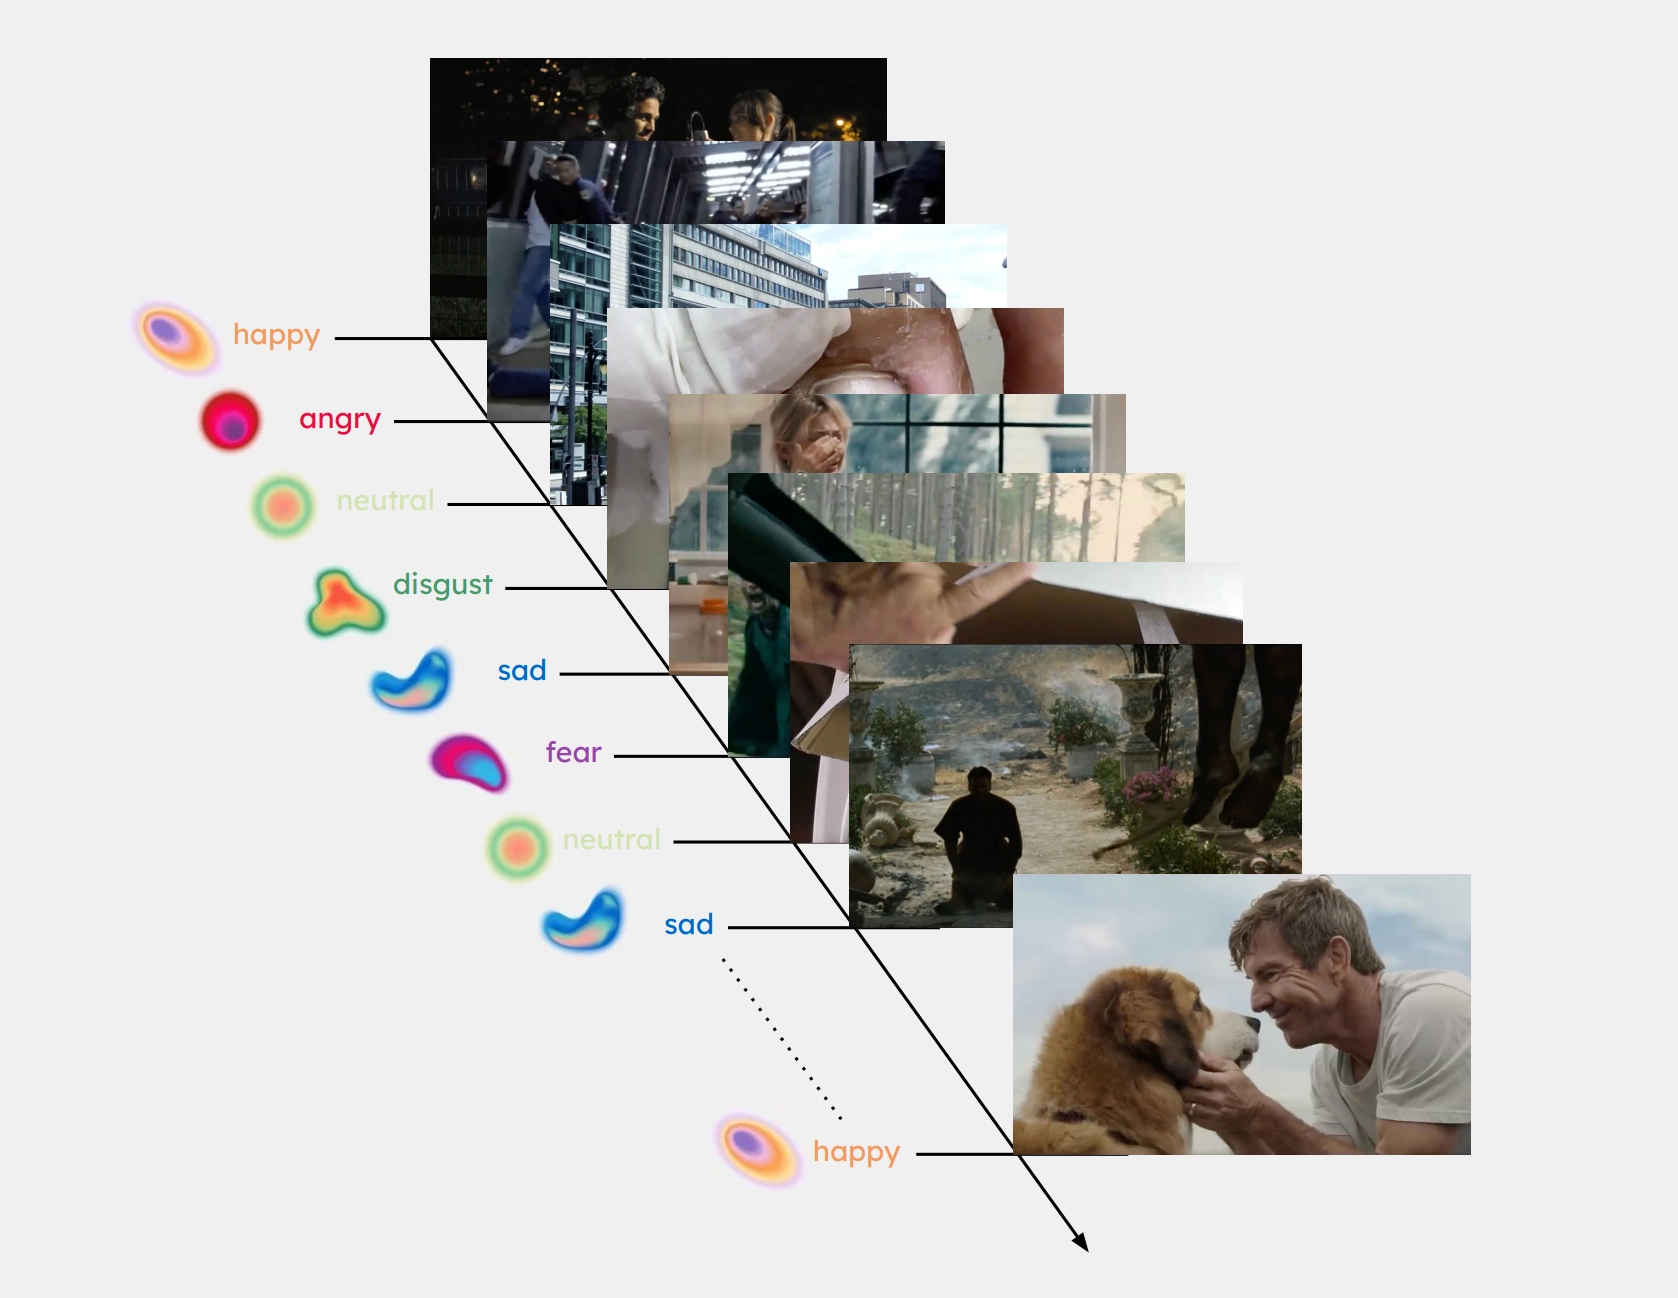
Each video is 1-5 minutes long, spanning 6 coarse categories: Anger, Sadness, Fear, Disgust, Happy, and Neutral (control). After multiple iterations, we landed on an experimental paradigm in which each ~1hr 15 min session contains 24 videos, 4 from each emotion category, presented in a shuffled block design. Between videos there are breaks for the participant to reset to baseline before proceeding to the next video. This randomized design prevents emotional carryover between videos while minimizing burnout as much as possible.
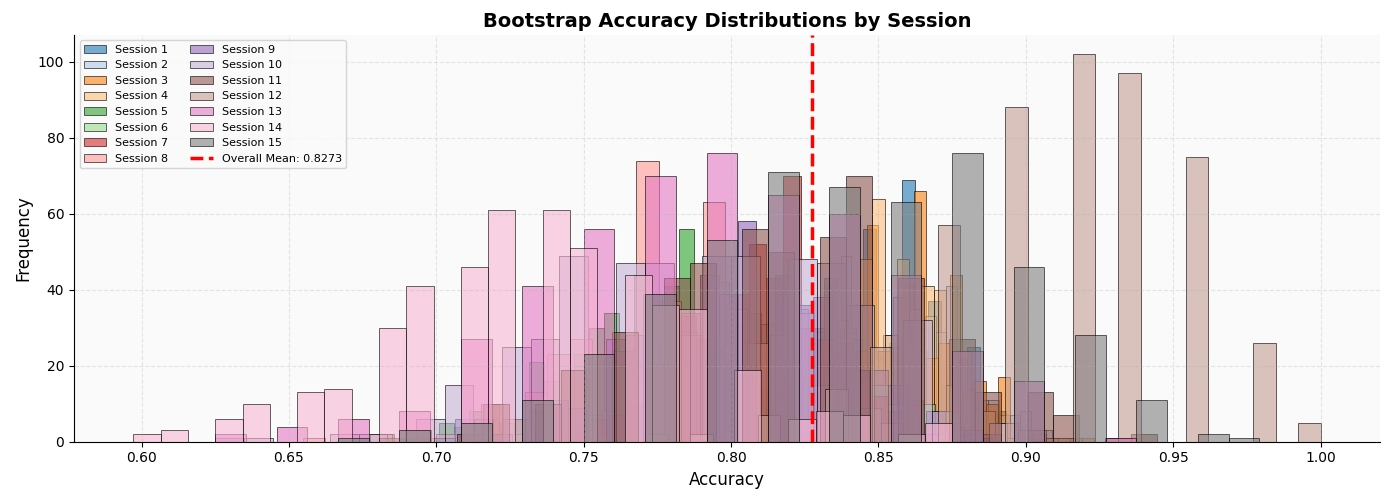
After each video, the participant rates how intensely they felt each of the 6 emotions on a scale of 1-10. Subjective labels are distilled from these ratings to provide a pseudo-ground-truth label. We achieve an 83% alignment rate between participants’ subjective labels and the intended target emotion, demonstrating that our videos reliably elicit the intended emotions across a variety of people.
Feature Spaces
Reliable labels are one half of our supervised learning equation; the other is how we extract meaningful signals from raw EEG data. EEG signals capture the spatio-temporal patterns of voltage oscillations across the scalp. The raw signal is rich, but how you represent it for modeling has a significant impact on what patterns are learnable. Some feature spaces preserve and highlight more relevant aspects of EEG’s dynamic signal than others.
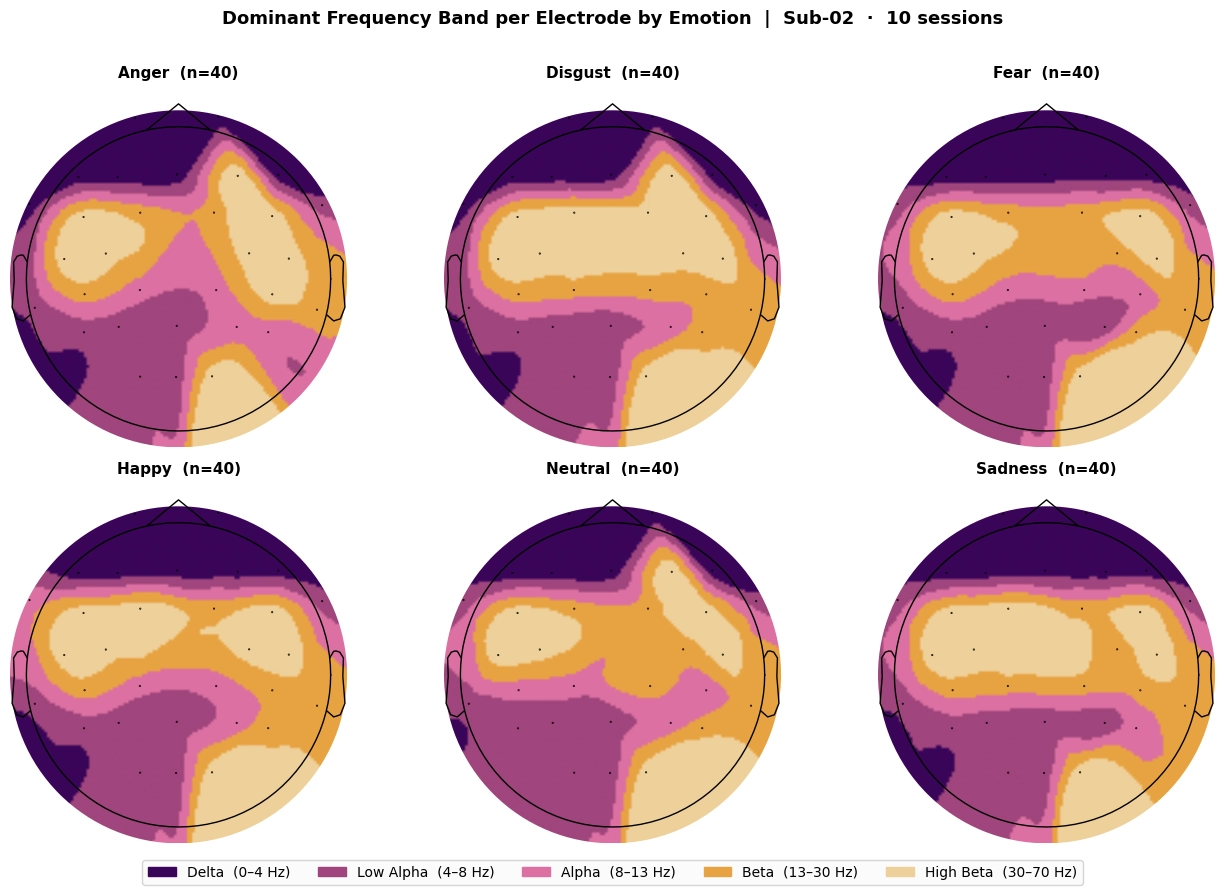
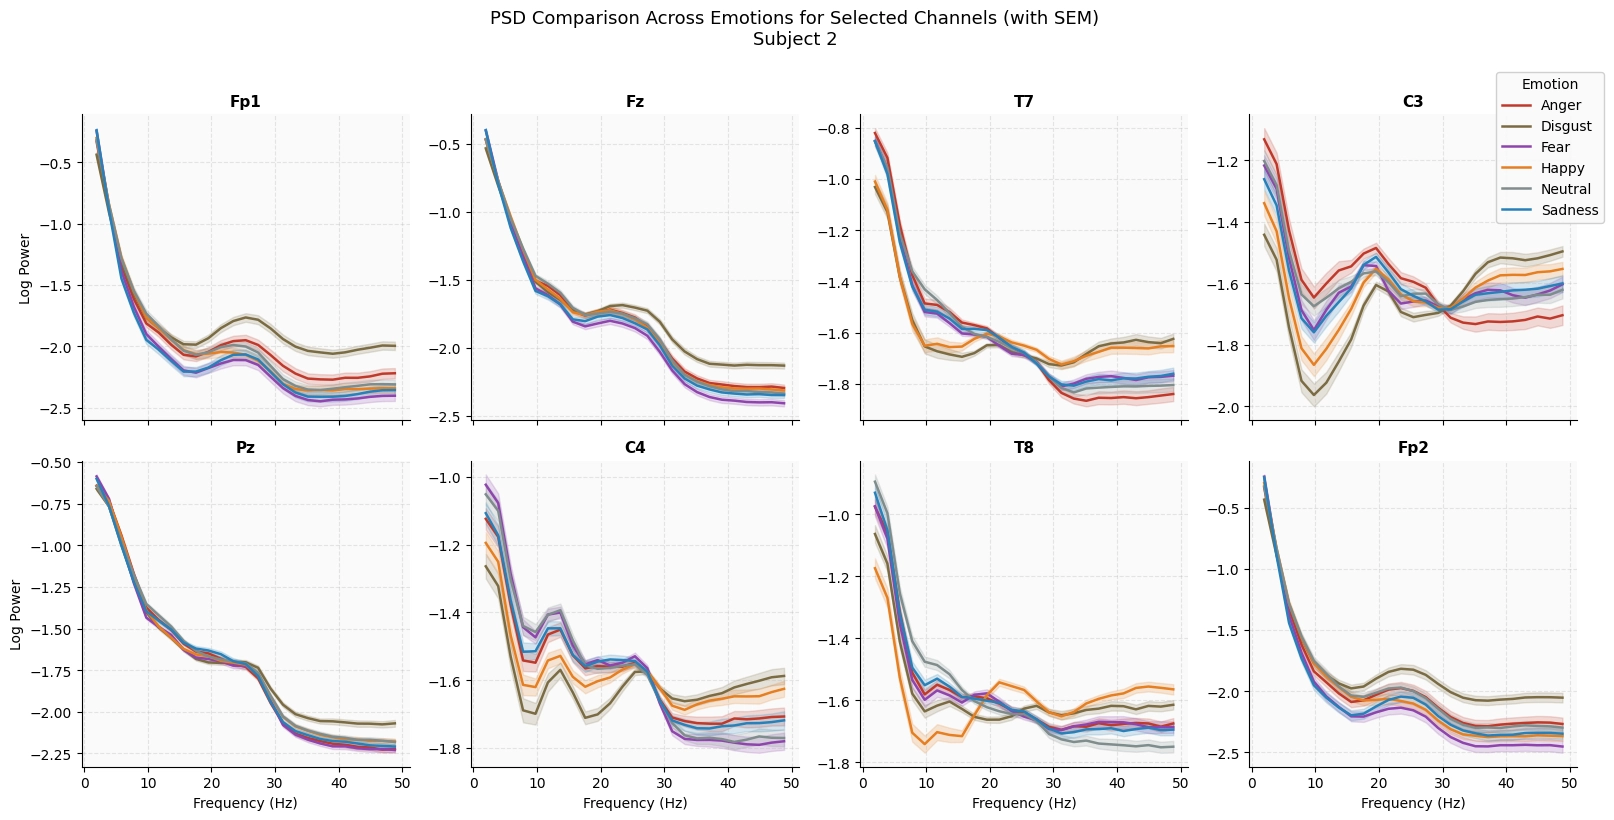
Much prior emotion research applies Differential Entropy (DE), a technique that compresses the signal into power estimates across five discrete frequency bands. While DE is computationally convenient, it discards much of the information that distinguishes emotional states from one another. In our analysis, we found the more expressive Power Spectral Density (PSD) operation to be a better-suited feature space. Rather than binning power into a handful of frequency buckets, PSD retains the full spectral fingerprint with up to 40x the granularity of DE. DE gives you ~5 features per electrode channel; PSD gives you ~200+.
Results
As an illustrative technique, we use a simple ridge classifier to showcase the decoding potential of NOVA. Each trial (video) is represented as a vector of ~6,231 PSD features across 31 electrode channels. Across many trials, the model identifies which frequencies at which electrode locations are reliably elevated or suppressed during a given emotional state. It then applies these learned signatures to predict the emotion class of a novel, unlabeled EEG segment.
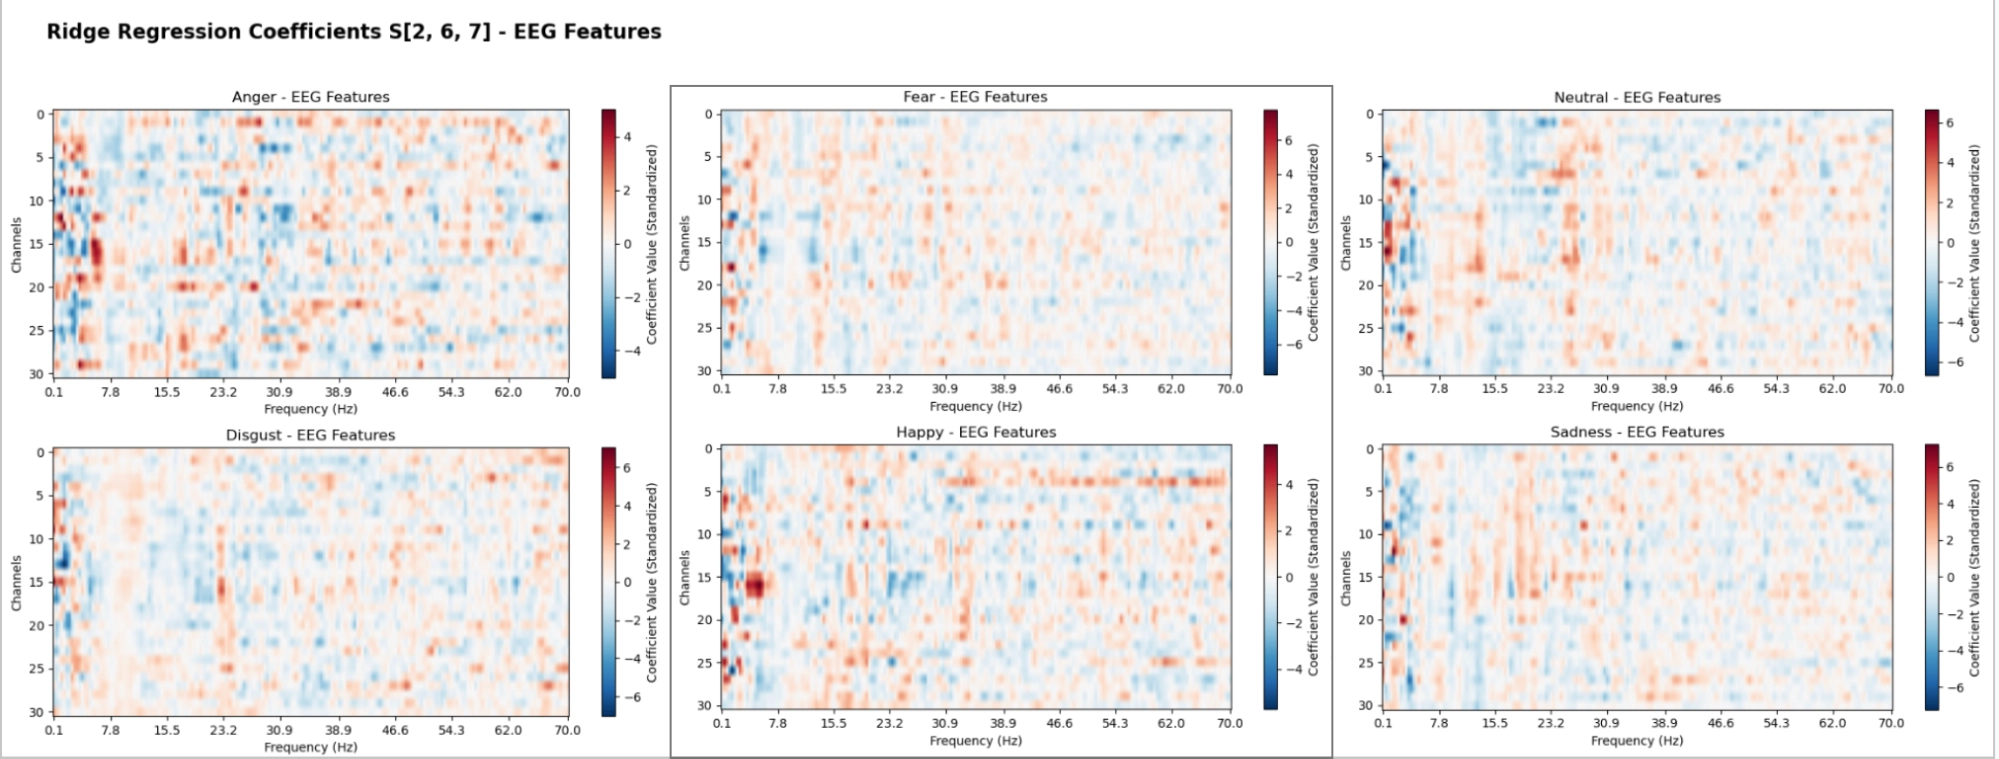
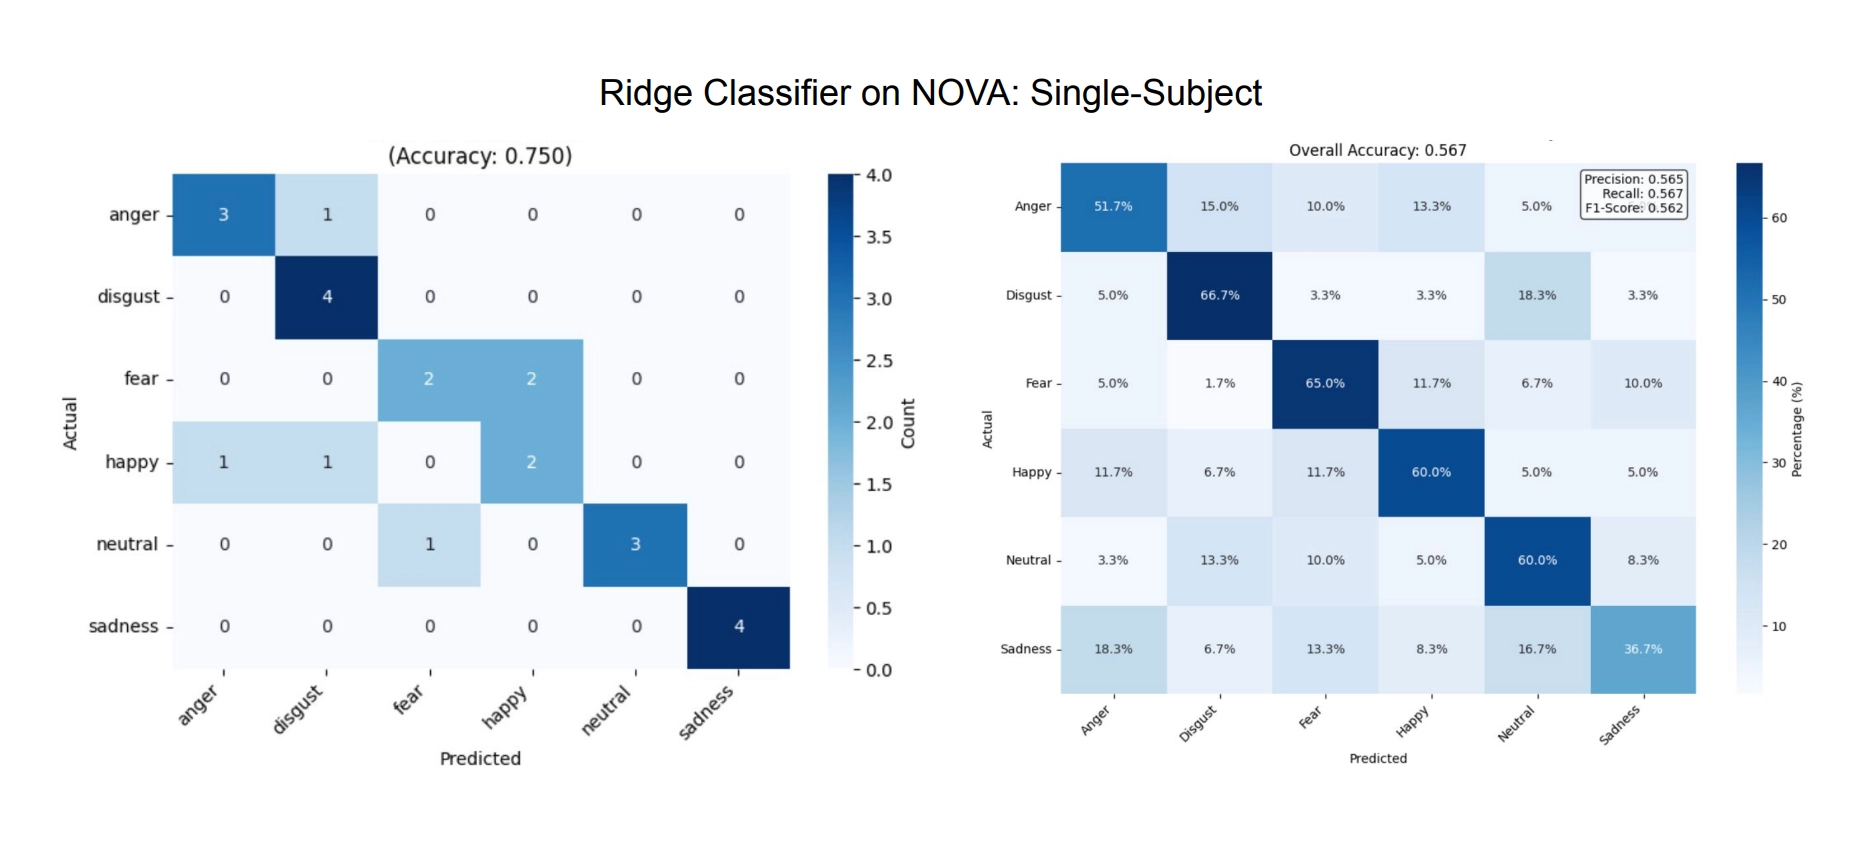
On this six-way classification task, random guessing yields 16.7%. We get up to 75% accuracy with a single-subject model. On average, across all participants, using session-wise cross-validation we get 46% accuracy. Using the simple ridge algorithm here lets the quality of the dataset speak for itself; impressive performance is achieved not with complex model architecture, but through deliberate experimental design and high-quality data. Careful analysis and iteration allowed us to distill where meaningful signals reside and how to represent them. When building robust systems from the ground up, starting with a meticulously clean and optimized dataset is crucial.
Future Directions
One of the biggest bottlenecks in the field of emotion research is the strenuous, draining, and time-intensive process of data collection. NOVA directly helps close this gap, providing a resource for downstream research that extends well beyond our own models.
Emotion is a layered and dynamic problem space, and one of critical importance as Alljoined builds increasingly nuanced representations of internal states. The complexity of this research provided us with deeper insight into how we should approach internal state decoding more broadly. Emotion is difficult to measure, guarantee and isolate. We also observed slow scaling behavior, suggesting we cannot rely on data volume alone to drive performance. For this reason, we believe the emotion data collected in NOVA will become increasingly powerful when integrated with our other ongoing multi-modal research threads.
Our preliminary results demonstrate state-of-the-art performance in EEG-based emotion decoding, laying the foundation for the next generation of affective computing devices and bringing us closer to reading the fabric of inner experience.